
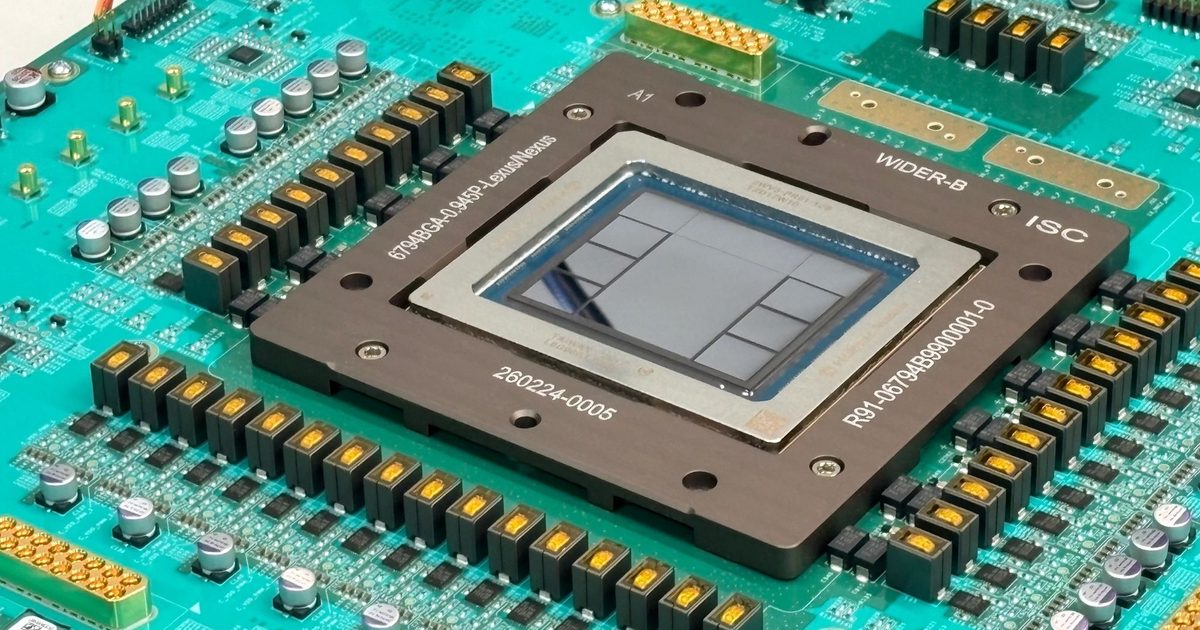
OpenAI has taken a significant step toward reshaping its hardware strategy with the introduction of Jalapeno, a custom AI chip designed specifically for the company's large language models. Developed in collaboration with Broadcom, Jalapeno is built for inference, the process that allows ChatGPT and other AI systems to generate responses to user queries. In benchmark results shared this week, OpenAI claims the chip performs dramatically faster and more efficiently than competing silicon, including products from Nvidia, the dominant player in AI accelerators.
What makes Jalapeno different
For years, OpenAI has relied heavily on Nvidia GPUs to train and run its models. Those GPUs work well for many tasks, but they were not originally designed for the very specific demands of modern large language models. Inference, in particular, requires moving enormous amounts of data through a system quickly while keeping energy consumption under control. Jalapeno was created with these exact workloads in mind. Instead of trying to serve every possible computing need, it is narrowly focused on the high-volume, high-speed computations required to power ChatGPT, Codex, the API, and future agentic products.
The chip is also notable because OpenAI used its own AI models to help design portions of it. This is not just a novelty; it allowed a small team to bring three additional AI models to full performance within just two months. That kind of rapid adaptation is becoming increasingly important as models evolve quickly and new capabilities are added on a regular basis. By designing hardware in-house and using AI to accelerate that design process, OpenAI is creating a tight feedback loop between software and silicon.
What the benchmark numbers show
OpenAI tested Jalapeno using InferenceX, an independent benchmark developed by SemiAnalysis, a respected semiconductor research firm. InferenceX measures how well a chip handles inference tasks, rather than the training side of AI. Across three different AI models, Jalapeno delivered between 1.5 and 1.9 times more AI work per watt of power compared to rival chips. That means for every unit of electricity consumed, Jalapeno can process significantly more queries or generate more tokens. In addition, latency, which is the time it takes for a chip to begin producing a response after receiving a prompt, was 1.7 to 3.6 times lower. For users, that translates into noticeably faster answers from ChatGPT and other AI-powered services.
The advantage becomes even more pronounced for highly interactive tasks, such as AI agents that need to reason, plan, and respond in near real-time. In those scenarios, Jalapeno performed up to 4.1 times better than competing hardware. This is particularly important because many in the industry believe that the next phase of AI growth will be driven by autonomous agents, which require extremely low latency to be useful in real-world applications. A slight delay can make an agent feel sluggish or untrustworthy, so the speed advantage of a purpose-built chip could be decisive.
Most chips force a tradeoff between speed and efficiency. A faster chip often burns more power, while a more efficient chip tends to be slower. OpenAI says Jalapeno manages to improve both simultaneously. The key, according to the company, is minimizing how much data needs to move between different parts of the system during processing. In many AI workloads, moving data is the bottleneck, not the actual computation. By keeping data closer to where it is processed and reducing unnecessary transfers, Jalapeno can operate at higher speeds while consuming less energy.
Why OpenAI decided to build its own chip
OpenAI has relied on Nvidia GPUs since its inception. Those GPUs have been essential for training the massive models that underpin ChatGPT, but they come with significant costs. GPU supply has been a persistent bottleneck, and the expense of building and operating large-scale AI infrastructure continues to grow. By designing its own chip, OpenAI gains more control over its supply chain, its performance characteristics, and its cost structure. It also reduces its dependence on a single supplier, which has been a strategic concern for many companies in the AI space.
The decision to focus Jalapeno on inference rather than training is a deliberate one. Training models is an extremely compute-heavy process that requires immense parallel processing power, and Nvidia has spent years optimizing its GPUs for that task. Inference, on the other hand, is the part of AI that runs continuously and at massive scale once a model is deployed. Every query to ChatGPT, every line of code generated by Codex, and every API call executes an inference workload. Even small improvements in inference efficiency can result in enormous cost savings and faster user experiences across millions of daily interactions.
OpenAI plans to deploy Jalapeno in small volumes by the end of 2026, with a meaningful scale-up in 2027. The company also confirmed that a second and third generation chip are already in development. That suggests OpenAI is making a long-term commitment to custom silicon, not just experimenting with a single product. As each generation improves, the company may expand the role of its in-house chips to more of its infrastructure, potentially including training workloads in the future.
Despite the strong results, OpenAI is not abandoning Nvidia anytime soon. Jalapeno currently handles only inference, and even that will be deployed gradually. Nvidia GPUs will still be needed for training new models and for many existing services. OpenAI will likely continue to buy Nvidia hardware in large quantities while also building out its own chip portfolio. The two approaches can coexist, at least for the foreseeable future.
The broader race to build custom AI chips
OpenAI is far from alone in this strategy. Google has long developed its own tensor processing units, or TPUs, to power its AI services. Amazon has been pushing into custom silicon with its Trainium and Inferentia chips, designed to handle both training and inference tasks. Anthropic, one of OpenAI's main rivals, recently confirmed that it has similar plans to build custom chips of its own. These companies have realized that depending entirely on commercial chip vendors like Nvidia can limit innovation, inflate costs, and create supply chain vulnerabilities.
The trend also extends to chip design itself. Samsung has reportedly used Anthropic's Claude AI assistant to speed up its own chip design work. AI models are increasingly being used to optimize the layout of circuits, improve power efficiency, and automate repetitive parts of the hardware engineering process. This is rapidly becoming an industry norm rather than an outlier. When a company like OpenAI uses its own models to design its own chips, it closes the loop: AI helps build the hardware that runs AI. That cycle could accelerate innovation at a pace that traditional chip development methods cannot match.
The shift toward custom silicon is also being driven by the changing nature of AI workloads. Early AI models were relatively small and could be handled by general-purpose processors. Modern large language models, however, involve billions or trillions of parameters and require specialized architectures to achieve acceptable performance. A chip designed for one specific model architecture can be optimized far more effectively than a general-purpose GPU. As model families continue to diverge and new capabilities like multimodal processing and long-context reasoning become standard, the benefits of custom silicon are likely to grow.
Jalapeno represents more than just a piece of hardware. It is a statement of intent from OpenAI that the company intends to be a leader not only in software but in the underlying infrastructure that powers artificial intelligence. The results published with InferenceX provide compelling evidence that purpose-built chips can deliver meaningful performance and efficiency gains over even the most established incumbents. As OpenAI prepares to scale up deployment in 2027 and pushes forward with its next-generation designs, the competitive landscape of AI hardware is poised for a major transformation. Companies that failed to invest in custom silicon may find themselves at a growing disadvantage in both performance and cost.
Source: Digital Trends News